
We have been building Model APIs on uRun that accept the same OpenAI- and Anthropic-compatible requests your code already sends, so moving to a new open model won’t mean rewriting the integration around it.
If your code already sends OpenAI Chat Completions requests, a uRun Model API is built to drop in as is, with no custom client or adapter to maintain.
What we have working
In the demo above, Qwen 3.8 27B runs on uRun and powers OpenCode, the open-source coding agent, through industry-standard chat completions. We have it working internally and are excited to share it with you soon.
Model APIs support four request formats, and which ones a given Model API accepts depends on its model (e.g. chat-style requests go to text and vision models, and real-time voice requests go to voice models).
How it will work
Once Model APIs open to customers, you won’t need to deploy anything. You’ll get an API key and send industry-standard requests to a running model.
Any tool that lets you set a custom OpenAI base URL can connect the same way, which is how OpenCode is set up as a custom provider in the video.
Rolling out model APIs worldwide
We are rolling Model APIs out across our GPU regions around the world.
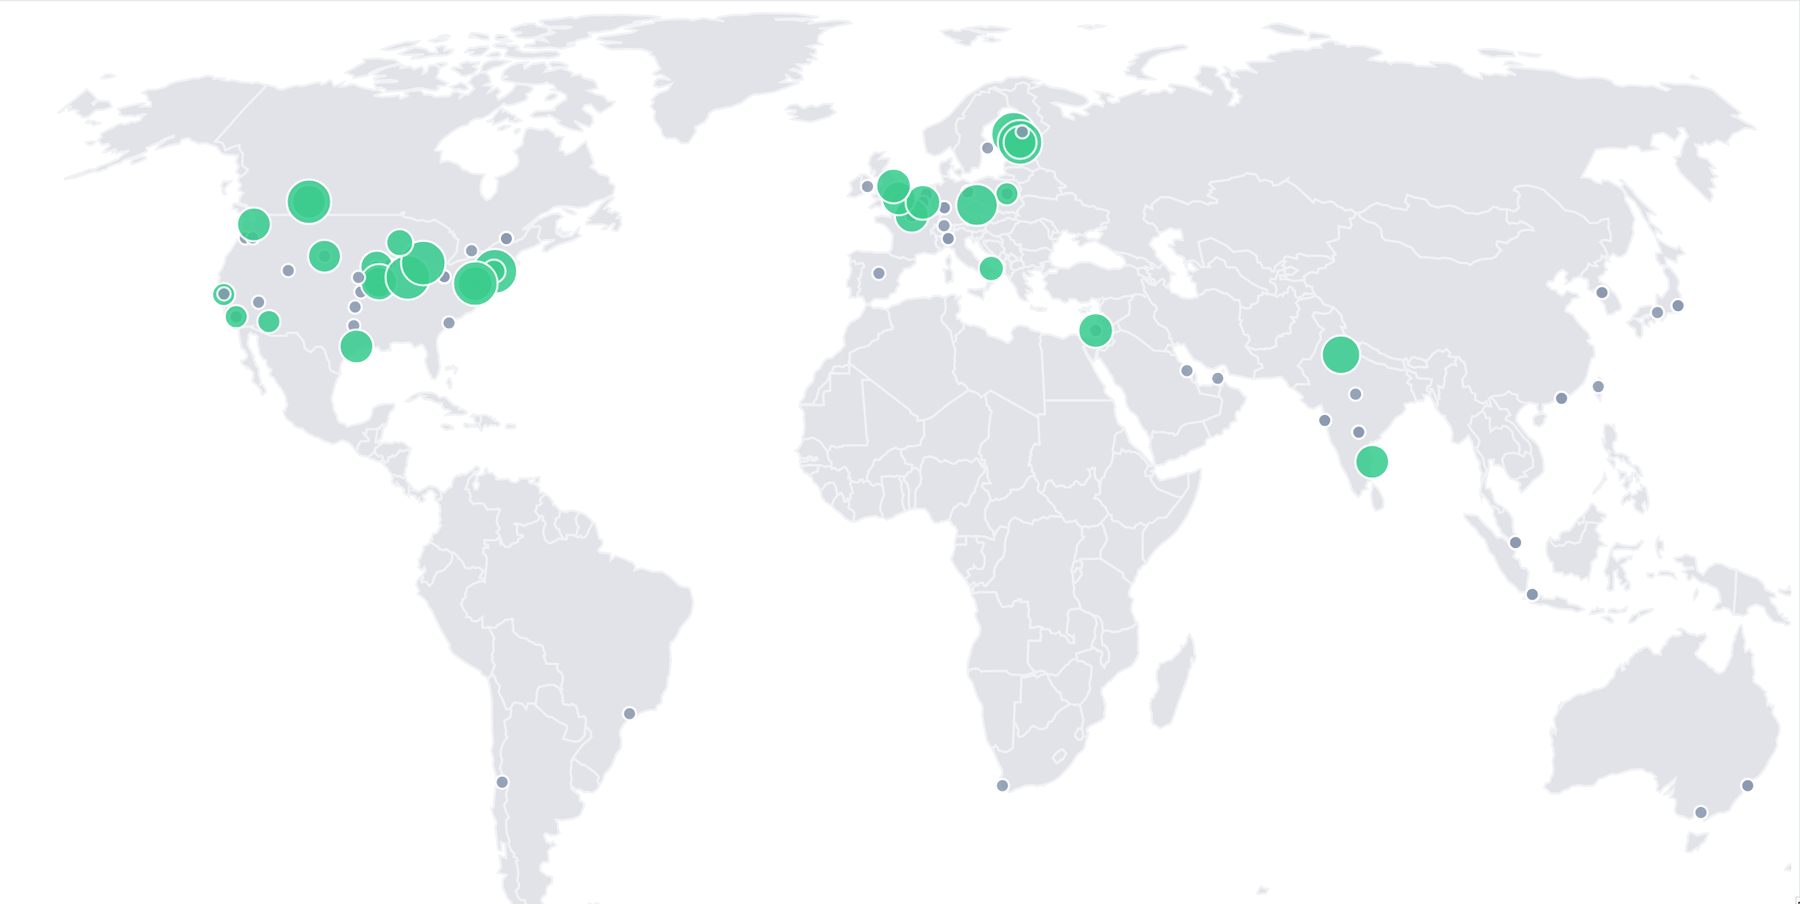
We can stand one up in a few minutes in any region where we have GPUs, so a Model API can run close to your users instead of routing every request to one data center.
Get early access
We’re opening up access to Model APIs to our waitlist first, which you can join here to get notified as soon as it opens.