
We’ve been benchmarking our Model APIs internally against OpenRouter and OpenAI, and the result that stands out is consistency. Across 16 identical requests, Qwen 3.8 27B on uRun streamed between 115 and 126 output tokens per second, while the same model through OpenRouter ranged from 94 to 778.
If you’re building a coding agent or a voice app, your users remember the slowest response, so how much a provider’s speed varies matters as much as its average.
What we tested
Using a small internal benchmarking tool, we sent the same 16 requests to three places: Qwen 3.8 27B on a uRun development server, the same model through OpenRouter, and GPT-5.4 mini on OpenAI as the closest equivalent. Every response was 128 output tokens long.
Results
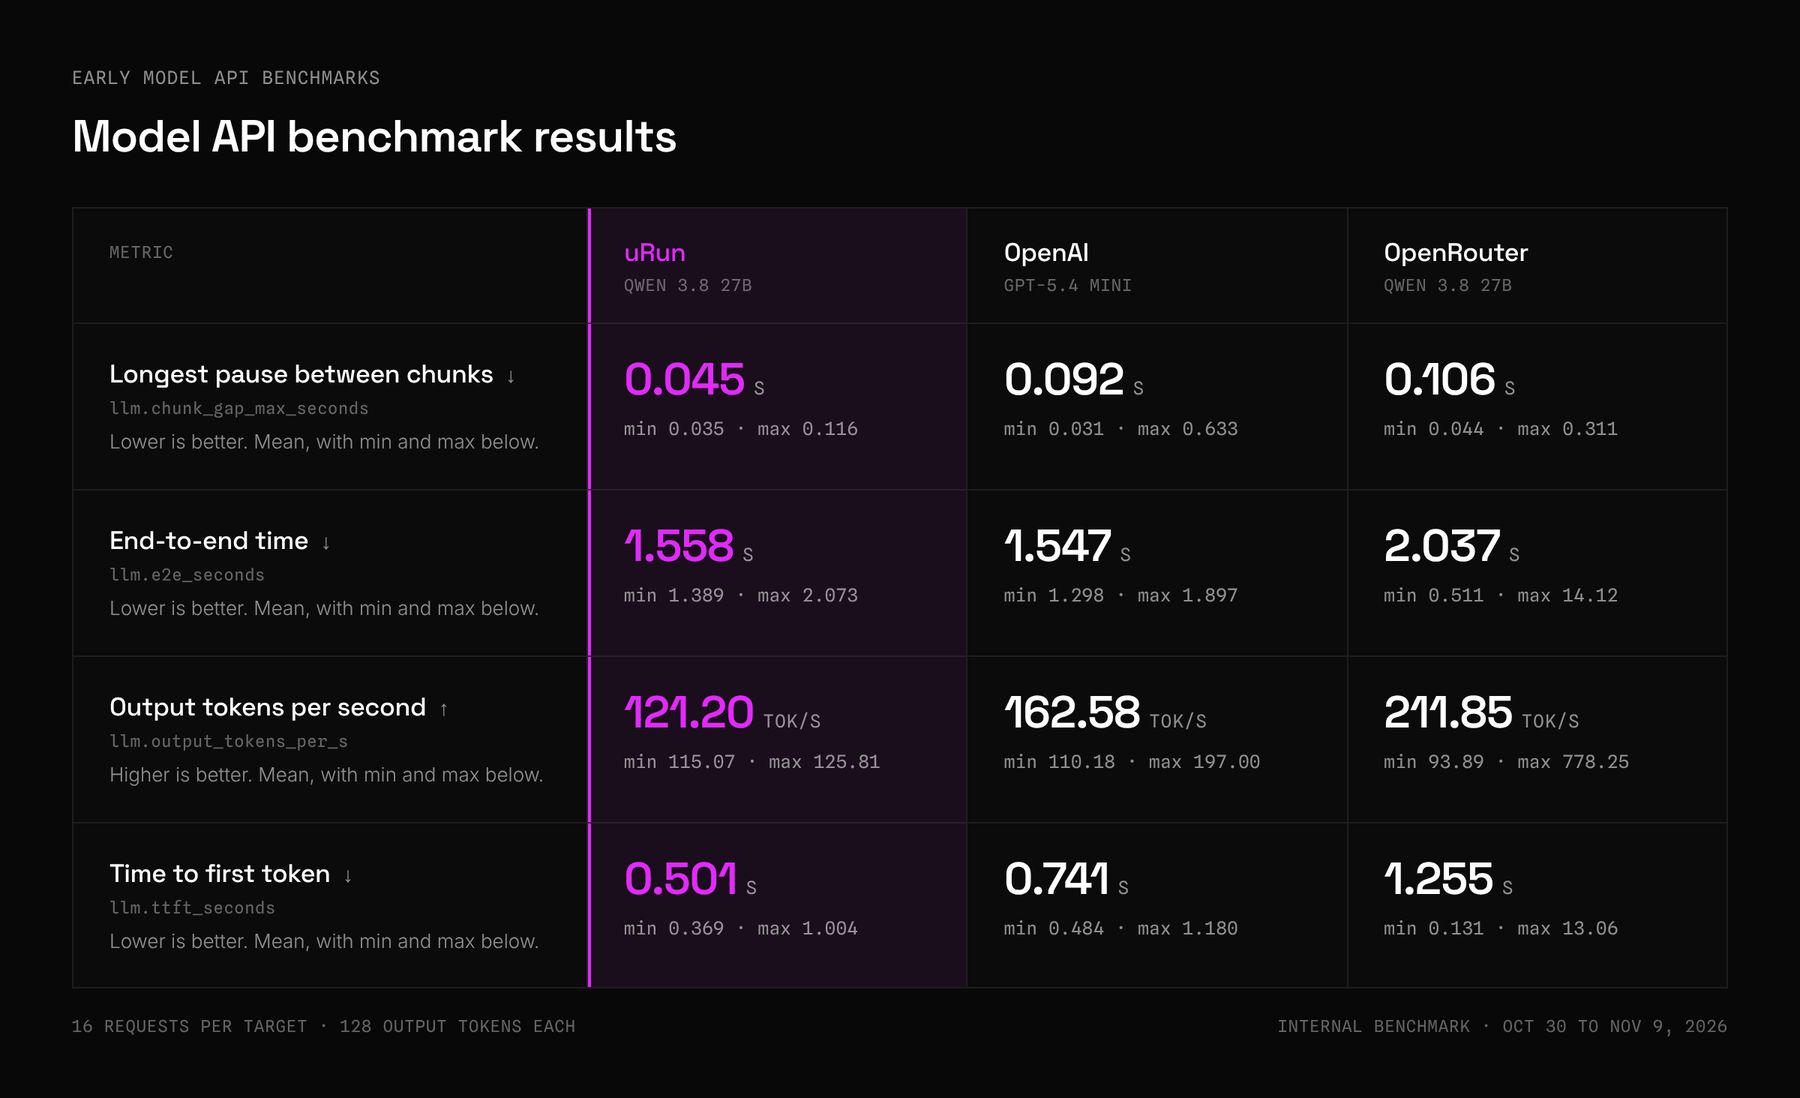
uRun’s fastest and slowest requests were less than 11 tokens per second apart (115.07 and 125.81), and it had the quickest average time to first token, at 0.501 seconds. It also streamed the most smoothly, with no pause between chunks longer than 0.116 seconds, compared with up to 0.633 seconds on OpenAI.
OpenRouter’s wide range comes from how it works. By default it spreads requests for a model across several providers, so two identical requests can land on very different hardware. In our run, that meant one response took 14.12 seconds to finish.
Where we’re taking these numbers
This run also showed us where to focus next. uRun averaged 121.20 output tokens per second, behind both OpenRouter and OpenAI, so we’re now tuning the stack to raise average throughput without giving up that consistency. Our goal is to lead every provider on these benchmarks, and we’ll publish fuller results as Model APIs roll out.
How we ran it
These are early results from a small internal run. Each target received 16 requests averaging 800 to 870 input tokens and returning 128 output tokens. The OpenAI, uRun and OpenRouter runs took place on Oct 30, Oct 31 and Nov 9, 2026.
Get early access
We’re opening up access to Model APIs to our waitlist first, which you can join here.
